Opus 5.5, Fable 5.1 and GPT-6 Astra all target demanding AI work. That does not make them equal choices for your next project. Price, tools, task quality and review time can point in different directions.
This comparison uses official documentation checked on September 23, 2026. It is a comparison of published specifications and workflow tradeoffs, not an independent benchmark. OpenAI's official name is GPT-6 Astra; we use that name throughout.
The published specifications
The table shows standard base API token rates in US dollars. M means one million tokens. It excludes cache discounts, special modes, tool charges and long-input surcharges.
Sources: Opus 5.5 specifications, Fable 5.1 specifications, and GPT-6 Astra specifications.
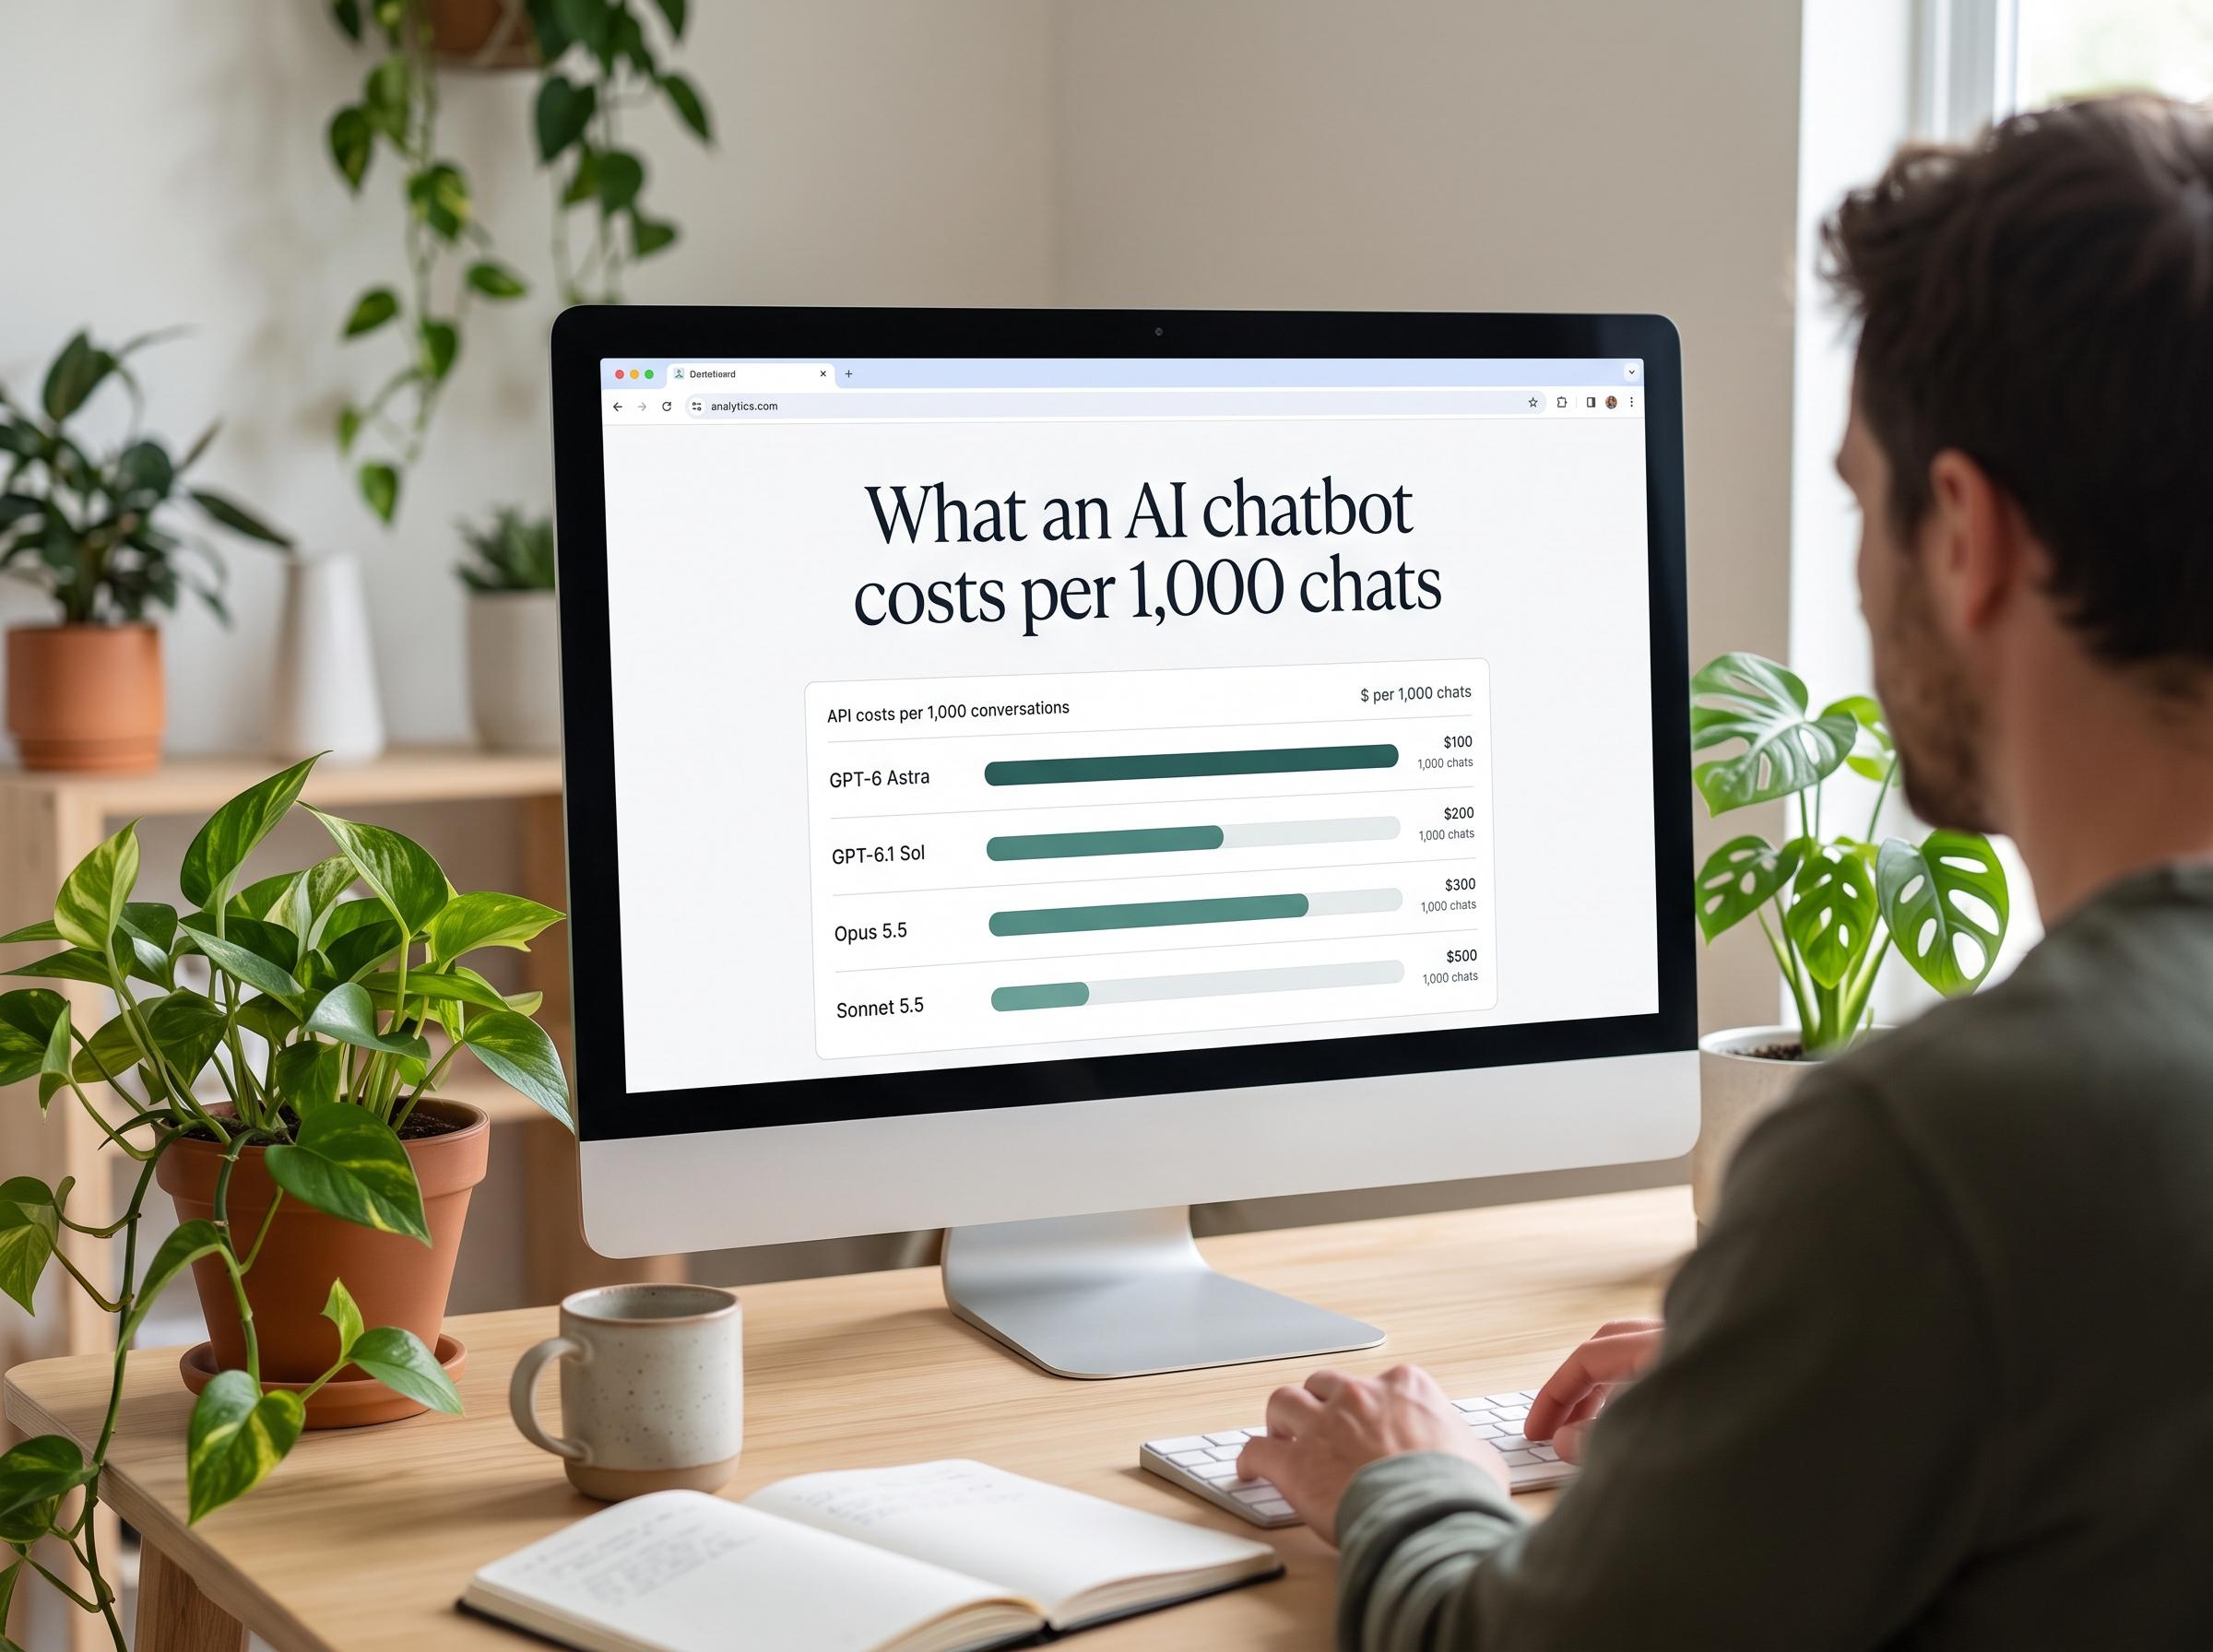
The price gap is clear. At the listed base rates, Opus costs 60% less per input or output token than the other two. That is arithmetic from the rates, not a claim that every finished task will cost 60% less.
Context limits are capacity limits. A slightly larger window is useful only if your task needs it and the model can use the material well.
Start with the task you need done
For a routine code change or document workflow, Opus 5.5 is a sensible first candidate to test when cost matters. That is our recommendation based on its lower listed rates, not a measured quality win.
Fable 5.1 is worth testing on work where errors remain after you have improved the brief and tested a less costly option. Anthropic positions it for demanding reasoning and long-running agent work. Decide whether any quality gain covers the higher bill.
Astra deserves a trial when your work already depends on OpenAI's tools and APIs. Its model page lists support for tools such as web search, file search and computer use through the Responses API. Existing integrations may save more effort than a small difference in model price.
Our AI integration service can help turn that shortlist into a bounded test. For more product context, see our Astra introduction.
Compare cost with one clear example
Assume each model uses 100,000 uncached input tokens and 10,000 billed output tokens. Use standard base rates, no tool calls and no retries.
- Opus 5.5: $0.40 input plus $0.20 output, for $0.60.
- Fable 5.1: $1.00 input plus $0.50 output, for $1.50.
- GPT-6 Astra: $1.00 input plus $0.50 output, for $1.50.
This is an illustration, not a prediction of token use. Providers tokenize text differently, and each model may take a different number of steps. Reasoning and retries can add billed output.
Astra also changes rates above 272,000 input tokens: input and cache rates double, while output rates rise by half for the full request. That threshold does not affect this example. Check your actual prompt size before pricing large-document work.
Isakatuparan ang mga ideyang ito.
Mula sa isang partikular na pag-aayos hanggang sa buong website, tutulungan ka naming linawin ang saklaw at maisagawa ito.
Pag-usapan ang website koCustom na Web at Application DevelopmentIbahagi ang iyong mga layunin. Karaniwan kaming tumutugon sa loob ng 4 na oras na may mga tanong at praktikal na susunod na hakbang.
Tools can change the answer
A model does not run an integration just because it can describe one. The surrounding app must provide tools, credentials, error handling and clear permissions.
If your workflow already works in one provider's stack, estimate the cost of moving it. Include tool schemas, streaming, saved conversation state, logging and tests. A lower token rate may take time to repay that work.
For Claude upgrades, inspect the current migration notes. Opus 5.5 and Fable 5.1 have model-specific rules around thinking and forced tool use. Do not assume an old request can switch model names without changes.
Our API and backend development service covers the engineering around these connections.
Do not pick a winner from one chart
A benchmark result depends on the task set, tools, prompts, effort settings and scoring rules. Vendor charts can help you choose what to test. They do not establish the best model for your site.
For example, a model may score well on code tasks but still mishandle your plugin's edge cases. A strong research answer may take too long for live customer support.
Use our earlier Astra and Claude comparison for historical context. Keep this newer decision tied to current documentation and your own results.
Run a fair trial in one afternoon
Choose ten tasks from recent work. Include common tasks, a few hard cases and one task where the correct response is to ask for missing information.
Give each model the same brief and source material. Record the exact model, tool access and effort setting. Use settings that fit the budget, and report any differences.
- Score whether the result is correct and complete.
- Record time to a usable answer, not just the first token.
- Count all calls, retries and tool fees.
- Note how long a person spends reviewing the result.
- Repeat close results so one lucky answer does not decide the choice.
Our workflow automation service can help capture these measures. Keep the first trial small enough that someone can review every output.
Choose a default and a reason to escalate
Your team may use one model for most work and another for a narrow class of hard tasks. Write down the signal that triggers a second attempt. A failed test or missing source is more useful than “this feels complex.”
Choose the model that meets your quality standard at an acceptable total cost. Recheck that choice when the workload, price or model changes.
Mga madalas itanong
Which model has the lowest base API token price?
Of these three, Opus 5.5 has the lowest published standard base rates as checked on September 23, 2026. Actual task costs also depend on token use, tools, retries and pricing options.
Are Fable 5.1 and GPT-6 Astra the same price?
Their listed standard base rates are both $10 per million input tokens and $50 per million output tokens. Cache pricing, long-input rules, tools and actual usage can differ.
Which model is best for coding?
This article does not establish a hands-on winner. Test the same real code tasks and compare passing tests, review effort, time and full cost.
Can I use more than one model in a workflow?
Yes. You can route tasks or escalate failed cases, but each integration needs testing. Preserve task context carefully and check the cost of extra attempts.