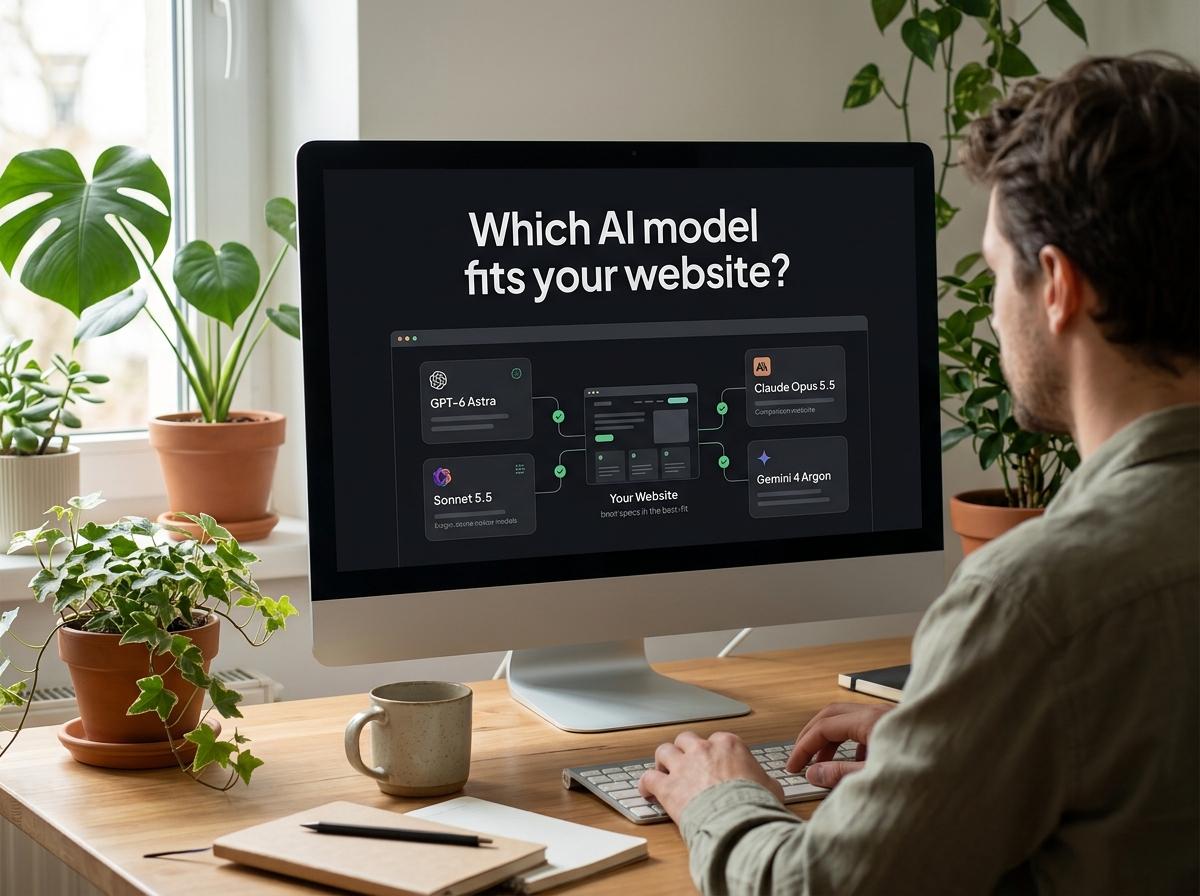
Five frontier-class models shipped between September 3 and September 30, 2026, and one of them, Gemini 4 Argon, is not yet open to the public. This guide compares them on what matters for a business website: price, access and the job you want done.
Our starting advice: shortlist a $2 / $10 model, either Claude Sonnet 5.5 or GPT-6.1 Sol, test it on your own tasks, and move to a flagship only where the cheaper model fails.
Compared at a glance
What an independent index shows
On the Vals Index, published September 30, Gemini 4 Argon scored 68.90% at $15.68 per test. Claude Sonnet 5.5 scored 67.04% at $21.34, Claude Opus 5.5 scored 66.97% at $32.14, and Claude Fable 5.1 scored 65.83% at $28.71.
Two things stand out. The top four sit within about three points of each other, and the cheaper Sonnet 5.5 scored above Opus 5.5 while costing less per test. Vals tests its own tasks, not yours, so treat the index as a starting point.
The models in short
- Claude Sonnet 5.5: $2 / $10, a 1M-token context window and 128K max output. Anthropic rates its latency as fast.
- Claude Opus 5.5: built for long-running agentic coding and knowledge work. Adaptive thinking is always on and cannot be disabled. Four breaking changes affect code written for Opus 5, so read our Opus 5.5 breaking changes guide before upgrading an integration.
- GPT-6 Astra: OpenAI's flagship at $10 / $50, with higher rates for long-context prompts ($20 / $75).
- GPT-6.1 Sol: the same $2 / $10 price as Sonnet 5.5. GPT-6 Luna costs $0.10 / $0.50 for high-volume work.
- Gemini 4 Argon: Google's newest model, aimed at long software engineering tasks, knowledge work and cyber defense. Read our Gemini 4 Argon explainer for access and pricing detail.
Which model for which website job
This table is a shortlist built from price tier and vendor positioning, not from our test results. Run each shortlisted model on 20 of your own tasks before you commit. Our blind-test kit shows how.
Put these ideas to work.
From a specific fix to a complete website, we can help you define the scope and get it done.
Discuss my websiteCustom Web & Application DevelopmentShare your goals. We typically reply within 4 hours with questions and practical next steps.
What it costs in practice
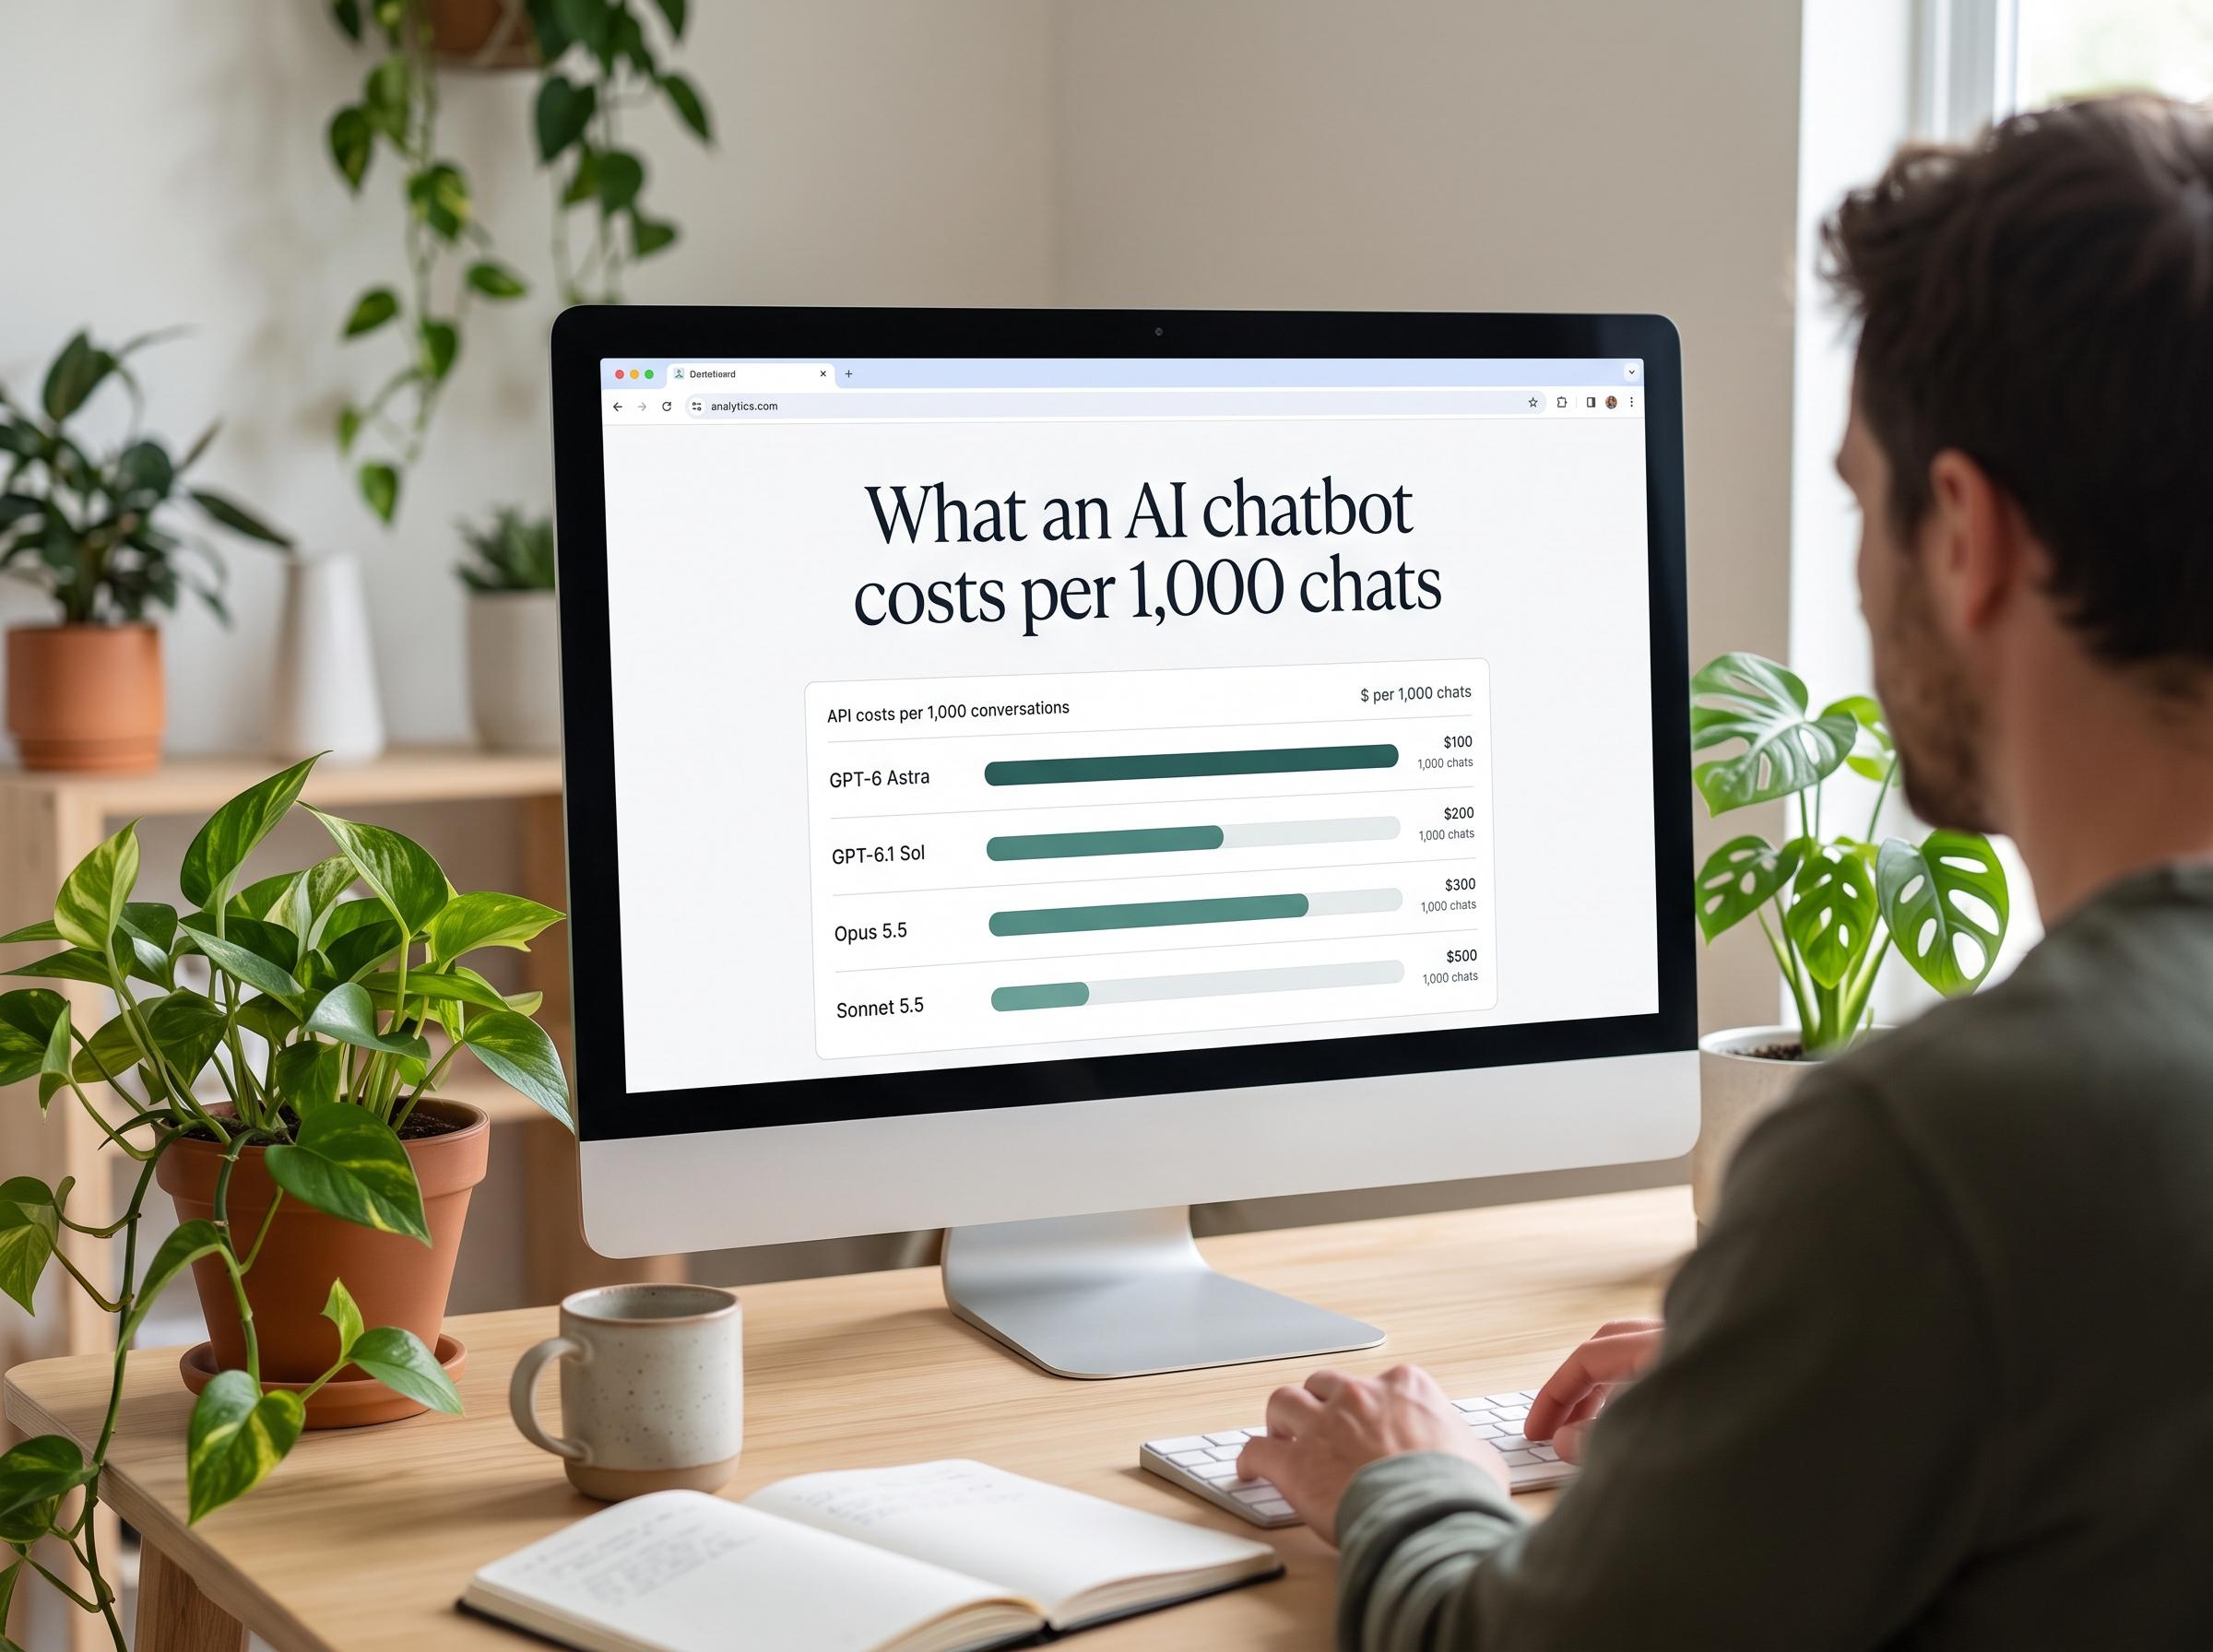
At 1,000 chats of 3,000 input and 500 output tokens, list prices come to about $11 on Sonnet 5.5 or GPT-6.1 Sol, $22 on Opus 5.5 and $55 on Astra, before caching. The full working is in our chatbot cost guide.
Integrate a model without locking yourself in
- Keep the model name in one config value, not scattered through the code.
- Send every request through one wrapper so a model swap is a one-line change.
- Log the token counts each API returns, per request.
- Set a monthly spend limit before launch.
- Keep a fallback model for outages and price changes.
Frequently asked questions
Which of these models is cheapest?
By list price, GPT-6 Luna at $0.10 / $0.50, then Claude Sonnet 5.5 and GPT-6.1 Sol at $2 / $10. Price per token is not cost per task: on the Vals Index, Sonnet 5.5 cost $21.34 per test against $32.14 for Opus 5.5.
Can I use Gemini 4 Argon today?
Not generally. Google is rolling it out first to trusted cyber defenders in its Fairwind Program and has not given a public date in the sources we checked.
Is Opus 5.5 a drop-in upgrade from Opus 5?
Not always. Anthropic lists four breaking changes for code already running on Opus 5: thinking cannot be disabled, forced tool use returns an error, thinking blocks are tied to the model and conversation, and the earlier computer-use tool is rejected on the Claude API and Google Cloud.
Which model should power a WordPress chatbot?
The cheapest model that passes your own accuracy test. Start with a $2 / $10 model, measure it on real questions from your site, and only pay for a flagship if the test shows a gap.
Choosing is the easy part
Picking a model takes an afternoon. Wiring it into WordPress or Next.js safely, with spend limits, logging and a fallback, is where projects stall. See our AI integration and chatbot development services.